Fine-Tuning Pretrained Language Models for Poker Strategy Using Reinforcement Learning
Published:
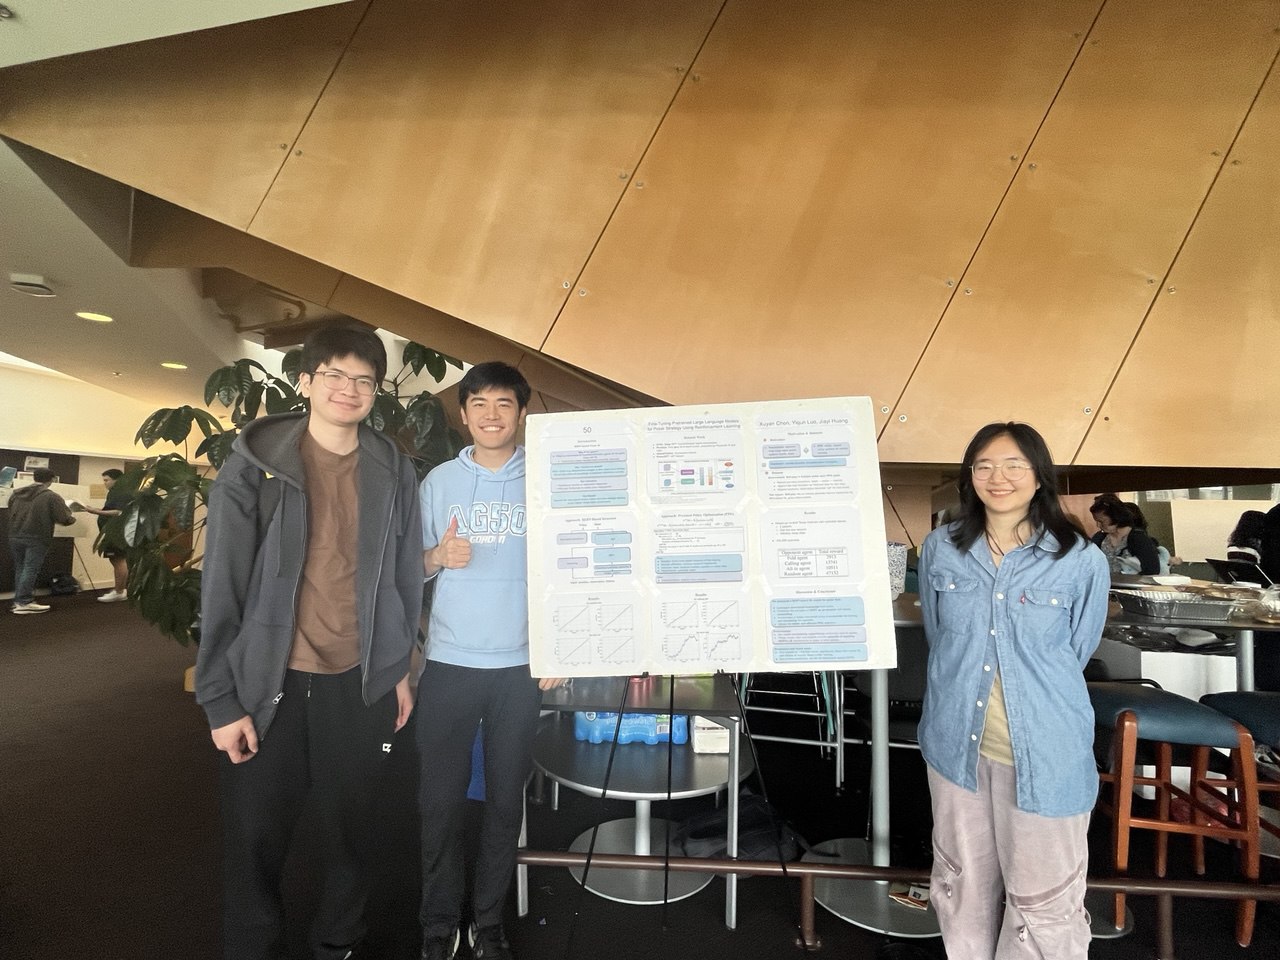
We are very honored to receive the best poster award at the Generative AI course project among 50+ groups!
The popularity and complexity of Texas Hold’em call for machine learning-based models, and rapid development of large language models (LLMs) as well as their application makes them a natural fit for Texas Hold’em formalism. We fine-tuned a BERT-based model for Texas Hold’em using proximal policy optimization (PPO) over around 100,000 hands, leveraging the pre-trained knowledge of LLMs along with the stability and efficiency of PPO. To accelerate the training and optimize the model structure, we combined the BERT encoding and direct embedding and incorporated a rule-based initialization. Our model consistently outperforms four benchmark agents, highlighting the potential of applying LLMs/BERT to Texas Hold’em and other game theory instances. Due to the limitations of the course project timeline and computing resources, further training with a larger number of hands may need to be done for future work to refine and evaluate the approach.